
Most enterprise agent pilots stall for one reason: a single prompt is asked to carry a process that spans five systems, an approval step, and an auditor’s questions six months later. The usual fix makes it worse, because teams bolt on more agents and more retries until costs climb and nobody can explain why the agent did what it did. Agentic design patterns solve this by giving each task a known control structure, from a simple tool-calling loop to a planner with a human checkpoint, each with predictable cost, latency, and failure modes. Matching the pattern to the process, not to the latest framework, is what moves a pilot into production.
Key Takeaways
|
What Are Agentic Design Patterns?
Agentic design patterns are structured ways for a large language model (LLM) to work through a task instead of answering in one turn: reasoning about the next step, calling a tool, checking a result, or delegating part of the job. Each pattern is a control structure, not a prompt template, so the same pattern can run on Claude, GPT, Gemini, or an open-weight model.
The vocabulary comes from two sources. Andrew Ng’s March 2024 letters in The Batch named four patterns: Reflection, Tool Use, Planning, and Multi-Agent Collaboration. Research papers supplied the mechanics, including ReAct (Yao and colleagues, 2022), which interleaves reasoning with actions, and Reflexion (Shinn and colleagues, 2023), which adds verbal self-critique.
A useful distinction separates workflows from agents. In a workflow, your code fixes the sequence of model and tool calls; in an agent, the model decides the sequence at run time. Most production systems mix both, and a deterministic backbone of AI workflow automation usually carries the parts that must never vary, such as approvals and record writes.
That distinction matters for budgets and audits. The more control you hand to the model, the more you pay in tokens and latency, and the more logging you need to explain an outcome afterwards. Choosing among agentic design patterns is therefore a governance decision as much as an engineering one.
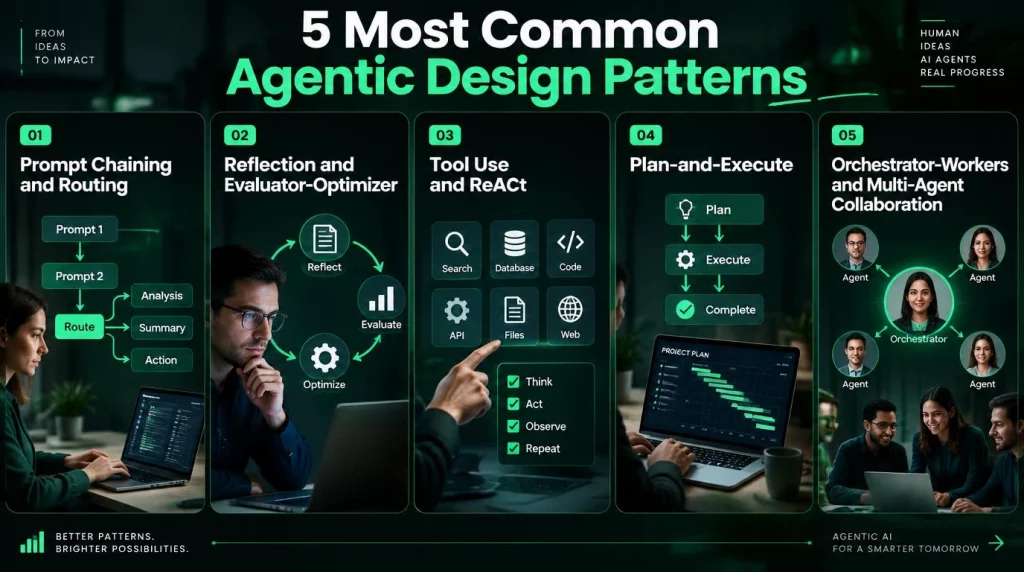
5 Most Common Agentic Design Patterns
Five pattern families cover nearly every agent in production today. They differ in who decides the next step, how many model calls a task needs, and where errors get caught, and most agentic design patterns you will see in vendor diagrams are combinations of these five.
Prompt Chaining and Routing
Prompt chaining splits a task into fixed steps, with each model call working on the previous output and a code check in between. Routing classifies an input first and sends it to a specialized prompt or model, for example sending password resets to a small model and contract questions to a stronger one.
Both are workflows in the strict sense. They are also the cheapest way to get reliable results, because every path can be tested before go-live.
Reflection and Evaluator-Optimizer
Reflection asks the model to critique its own draft and revise it. The Reflexion paper reported 91 percent pass@1 on the HumanEval coding benchmark, against 80 percent for GPT-4 alone, by letting the agent learn from test feedback across attempts.
The evaluator-optimizer variant uses a second model or prompt as the critic. Among agentic design patterns that revise output, it is the easiest to audit, because the quality standard is explicit and the critique itself becomes a logged artifact.
Tool Use and ReAct
Tool Use lets the model call functions, APIs, or databases through typed schemas instead of answering from memory. ReAct is the loop that runs most tool-using agents: the model reasons, picks an action, reads the observation, and reasons again until it reaches an answer or a step limit.
Native function calling in current models replaced the text parsing of the original paper. The loop itself is unchanged, and it remains the default for tasks where each next step depends on what the last tool returned.
Plan-and-Execute
The Plan-and-Execute pattern separates planning from doing. A planner writes the full list of steps first, and an executor carries them out, often with a cheaper model.
ReWOO (Xu and colleagues, 2023) showed why this matters for cost: by planning tool calls up front instead of re-reading every observation, it used about five times fewer tokens than ReAct on the HotpotQA benchmark. A written plan is also something a person can approve before anything happens, which is why regulated teams often prefer it over other agentic design patterns.
Orchestrator-Workers and Multi-Agent Collaboration
Multi-agent collaboration gives separate agents separate roles, usually with an orchestrator that splits the task, sends parts to worker agents, and merges the results. Anthropic reported in June 2025 that its multi-agent research system, with Claude Opus 4 leading Claude Sonnet 4 subagents, outperformed a single Claude Opus 4 agent by 90.2 percent on its internal research evaluation.
The same report noted that its multi-agent setup used about 15 times the tokens of a chat interaction. Gartner predicted in August 2025 that one third of agentic AI implementations will combine agents with different skills by 2027, which is a reason to design for collaboration among agentic design patterns, not a reason to start with it.
When to Use Each Pattern
Three questions decide which of the agentic design patterns fits a task, and they work best in order. The answers narrow the choice before any framework debate starts.
- Question 1, known steps: If the steps are known in advance, a prompt chain or a routed workflow is enough, and the model only supplies judgment inside each step. If they are not, the model has to choose steps, which points to ReAct for short tasks or Plan-and-Execute when the plan should be approved first.
- Question 2, objective checks: If tests, schemas, business rules, or a reference answer exist, an evaluator-optimizer loop adds real quality. If the only judge is the same model’s opinion, reflection mostly adds cost.
- Question 3, independent parts: If parts of the work can run in parallel or need different permissions, orchestrator-workers earns its token cost. If every step depends on the last, one agent with good tools is usually faster and cheaper.
Anthropic’s engineering guide Building effective agents, published in December 2024, reaches the same conclusion from the other direction. It advises finding the simplest solution possible and adding multi-step agentic systems only when simpler ones fall short, a rule that applies to every one of the agentic design patterns above.
| Enterprise process | Pattern | Why it fits | Human checkpoint |
|---|---|---|---|
| Invoice matching and posting | Prompt chain with schema checks | The steps are fixed and the model only reads documents | Exceptions above a set tolerance |
| Customer request triage | Routing | Requests fall into known categories with different handlers | Low-confidence classifications |
| Contract clause review | Evaluator-optimizer | Each clause can be checked against a clause playbook | Final legal sign-off |
| IT incident diagnosis | ReAct with tools | Each next step depends on the log or metric just read | Any change to production systems |
| Vendor onboarding | Plan-and-Execute | Steps vary by vendor type, and the plan can be approved first | Approval of the plan before execution |
| Market or due-diligence research | Orchestrator-workers | Sources can be searched in parallel and merged | Analyst review of conclusions |
Mapping your own backlog this way usually shows that most processes need the cheaper agentic design patterns. Teams that lay these flows out in an AI agent workflow builder can see the pattern, the tools, and the checkpoints on one canvas, which shortens the review with risk and compliance teams.
Implementation Considerations for Agentic Design Patterns
Agentic design patterns place specific demands on the platform around the model, and those demands decide whether an agent passes an architecture review. Four requirements come up in almost every enterprise evaluation.
- Orchestration with state: The platform sequences calls between agents and tools and survives failures and retries without losing the task’s state.
- Audit trail: Every plan, tool call, and revision gets a timestamped record that a compliance officer can read without engineering help.
- Approval gates: High-stakes actions, such as releasing funds or sending customer communications, wait for a human decision before execution.
- Deployment flexibility: Workloads with residency rules run on-premise or in a private cloud, while lower-risk agents run as SaaS, without a rebuild.
Tool governance deserves its own design. Each tool needs a typed schema, input validation, scoped permissions, and a log of every call, because an agent is only as safe as the most powerful tool it can reach. A registry of approved tools is the practical control, rather than letting the model call anything an API key allows.
Reflection creates a quieter risk. A revision loop that overwrites the first draft leaves an audit gap, so regulated teams should keep each version and the critique that produced the change. Policies written around agentic design patterns, such as “every plan is reviewable” or “every revision keeps its original”, also survive model upgrades better than policies written around one vendor’s model.
The build versus buy question follows from the same list. One Reflection or Plan-and-Execute loop for one use case is a realistic project for a small team. Maintaining orchestration, audit logging, and approval tooling across dozens of workflows is a platform commitment that rarely shows up in the proof-of-concept budget.
Trade-offs and Failure Modes
Every one of the agentic design patterns buys reliability or autonomy with tokens, latency, or new ways to fail. The table compares them using published research where it exists and relative estimates where it does not.
| Pattern | Relative token cost | Latency profile | Typical failure mode |
|---|---|---|---|
| Prompt chain or routing | Lowest, one call per step | Predictable, with a fixed number of calls | A misrouted input gets a confident wrong answer |
| ReAct with tools | Medium, growing with every step and observation | Variable, depending on loop length | Loops, repeated tool calls, or acting on a bad observation |
| Plan-and-Execute | Lower than ReAct; ReWOO used about 5x fewer tokens on HotpotQA | A planning delay up front, then fast execution | A stale plan when conditions change mid-run |
| Reflection or evaluator-optimizer | Each round adds at least a critique call and a revision call | Grows with every round | Endless polishing, or a critic that approves its own errors |
| Multi-agent collaboration | Highest, about 15x a chat interaction in Anthropic’s system | Parallel workers cut wall-clock time, while coordination adds overhead | Lost context between agents, duplicated work, conflicting outputs |
Single-agent versions of agentic design patterns are not cheap either. Anthropic’s June 2025 report puts a single agent at about four times the tokens of a chat interaction, and it found that token usage alone explained 80 percent of performance variance on the BrowseComp evaluation. More tokens buy better answers, up to the point where the bill no longer matches the task’s value.
Reliability compounds across steps. The tau-bench study (Yao and colleagues, 2024) found that GPT-4o completed fewer than half of its retail customer-service tasks, and that its pass^8 score, the chance of succeeding on all of eight repeated attempts, fell below 25 percent. Agentic design patterns that add steps also add chances to fail, so step limits, timeouts, and a fallback to a person belong in every design.
Self-correction has limits too. Huang and colleagues showed at ICLR 2024 that LLMs often fail to improve their reasoning through intrinsic self-correction when no external feedback is available, and sometimes make answers worse. Reflection pays off when the critic has tests, rules, or retrieved evidence to check against.
The cheapest safety net is a person at the right step. Approval gates at the plan, before irreversible tool calls, and at handoffs between agents catch most of the failures above without slowing every task, and our guide to multi-agent orchestration covers how those handoffs are coordinated and logged.
5 Emerging Agentic Design Patterns in the Future
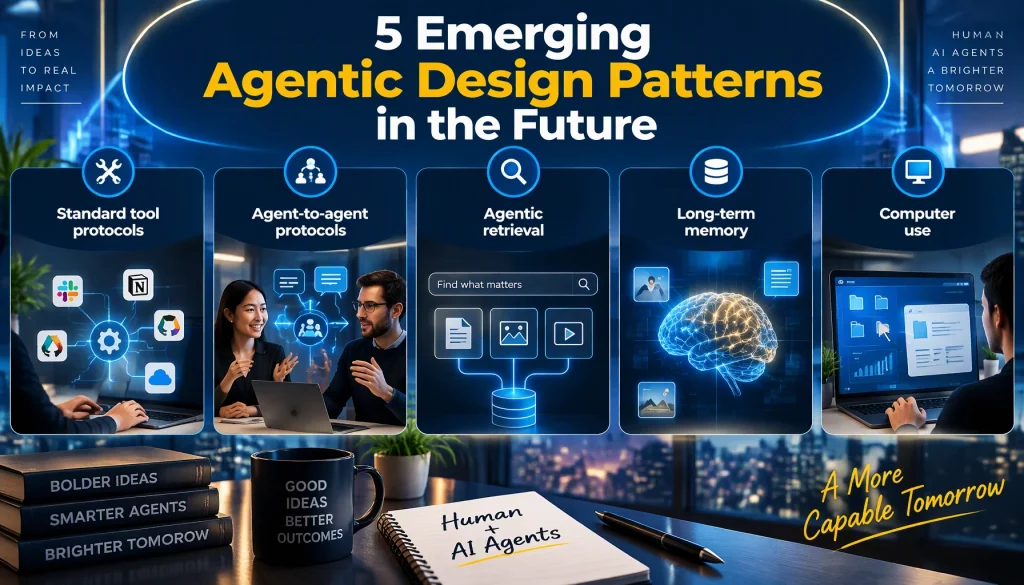
The newest agentic design patterns are less about reasoning loops and more about standard interfaces, memory, and agents that operate software directly. Five developments are worth tracking.
- Standard tool protocols: Anthropic released the Model Context Protocol (MCP) in November 2024 to standardize how agents connect to tools and data, and in December 2025 moved it to the Linux Foundation’s Agentic AI Foundation, which turns Tool Use from custom glue code into a shared interface.
- Agent-to-agent protocols: Google introduced the Agent2Agent (A2A) protocol in April 2025 so agents from different vendors can discover each other and exchange tasks, and the protocol moved to the Linux Foundation in June 2025.
- Agentic retrieval: The agent decides when to search, rewrites the query, and checks whether the results answer the question, instead of running one retrieval step before answering.
- Long-term memory: Agents store facts, preferences, and past outcomes between sessions, which raises new questions about retention and deletion.
- Computer use: Agents operate browsers and desktop apps through clicks and keystrokes, which helps with legacy systems that have no API but adds a large new attack surface.
Agentic retrieval is the one most enterprises meet first, because policy, contract, and product knowledge sits in documents. A grounded setup such as Claude RAG is the usual starting point, and the agentic version adds a loop that judges whether the retrieved passages are good enough before the model answers.
Which Patterns Hold Up in Production, and Which Stay in Papers?
The gap between research demos and production systems is wide, and it decides which agentic design patterns your team should invest in first. Public evidence points in a consistent direction.
| Pattern | Production track record | Where it struggles |
|---|---|---|
| Routing and prompt chains | Widely used for triage, extraction, and drafting, because behavior is predictable and testable | Tasks with steps nobody can list in advance |
| Tool use with typed schemas | The core of most deployed agents, now standardized through MCP | Tools with broad permissions and weak validation |
| Evaluator-optimizer with objective checks | Strong where tests or rules exist, as the Reflexion coding results show | Open-ended writing judged only by another model |
| Orchestrator-workers for research | Proven in Anthropic’s system on broad, parallel research questions | Tightly coupled work such as most coding, by Anthropic’s own account |
| Fully autonomous open-ended planning | Popular in 2023 demos such as AutoGPT | Long tasks without checkpoints, where errors compound |
Cost and value decide survival more than accuracy does. Gartner predicted in June 2025 that over 40 percent of agentic AI projects will be canceled by the end of 2027 because of escalating costs, unclear business value, or inadequate risk controls. It also estimated that only about 130 of the thousands of vendors claiming agentic capability offer real agents.
Adoption is still climbing. McKinsey’s 2026 State of AI survey found 40 percent of large companies scaling agents, up from 27 percent a year earlier. The organizations that scale tend to begin with narrow agentic design patterns and add autonomy only after the logs show it is safe.
A vendor that claims support for these patterns should be able to show five things in a live demo, not on a slide:
- Reflection log: Both the draft and the revision are retained, with the critique that caused the change.
- Tool registry: Approved tools have schemas, input validation, and scoped permissions.
- Reviewable plan: The system produces a human-readable plan that a reviewer can approve or reject before execution.
- Real orchestration: Agent handoffs run through an orchestration layer with state and retries, not prompts stitched together by hand.
- Deployment options: The same agent can run on-premise for a regulated workload and as SaaS for a lower-risk one.
Conclusion
Agentic design patterns give your team a shared vocabulary for deciding how much autonomy each task deserves. Chains and routing cover predictable work, ReAct and Plan-and-Execute handle variable steps, evaluator loops pay off when output can be checked, and multi-agent systems earn their cost only on broad, parallel work. This quarter, your team can list its ten highest-volume processes, run each through the three questions, and pilot the cheapest pattern that passes.
The next question is how those patterns run under one governance layer as the portfolio grows, with shared tool registries, audit trails, and approval gates instead of one-off scripts. To see how orchestration, logging, and on-premise deployment fit together, explore the AI Hive platform features built for enterprise agent workloads.